How Does an AI Receptionist Work? Every Step of a Call, Explained
This guide walks through what happens, step by step, from the moment a caller dials to the summary landing on your phone. If you are after the service itself, see our AI receptionist page. New to the idea? Start with what an AI receptionist is, or read how to build an AI receptionist if you are weighing up doing it yourself.
Quick Answer
In plain English: an AI receptionist answers your business number the way a good front desk person would. It picks up every call, day or night, works out what the caller needs, books the appointment or takes the message, passes urgent calls to a person, and texts and emails you a summary the moment the call ends. It can take several calls at once.
Under the hood, an AI receptionist works by combining three core technologies in a “cascading architecture”: speech-to-text converts the caller's voice to text, a large language model (like GPT-4 or Claude) processes the text and generates a response, and text-to-speech converts the response back into spoken audio, all in real time. The full loop typically completes in 600-900 milliseconds (sub-second), which is faster than most humans respond in conversation.
The six steps in every AI receptionist call:
- Call routing: your business number forwards to the AI's virtual line via SIP/VoIP (often through Twilio)
- Speech-to-text (STT): services like OpenAI Whisper, Deepgram, or Google Speech-to-Text transcribe the caller's words in real time at ~95%+ accuracy
- Large language model (LLM): GPT-4, Claude, or Gemini processes the transcript with your business context and generates the appropriate response
- Text-to-speech (TTS): ElevenLabs, Cartesia, Azure Speech, or similar converts the response to natural-sounding audio (Australian accent for AAA)
- Workflow actions: in parallel, the AI triggers actions in your business software (book the appointment, log the lead, send SMS)
- Call summary: when the call ends, a transcript and structured summary are generated and sent to your team within 60 seconds
For Australian businesses, the technical details matter because they determine whether the AI receptionist sounds natural (low latency under 500ms feels human; over 1,000ms feels robotic), handles complex industry workflows (function calling and API integration depth), and handles caller data in line with the Privacy Act 1988 (Cth) (which models are used, where data is processed, and how it's protected).
You don't have to build any of this yourself. Aussie AI Agency runs it as a done-for-you service: we set up and tune your AI receptionist, have it live within 3 business days, and plans start from $149/mo (ex GST), month-to-month. Book a free 30-minute demo to hear it handle a call.
No obligation · Niel calls you to book a time
Plans from $149/month + GST.
Hear it handle real calls, then get one built for your business
Press play to hear our AI receptionist on real calls. Then tell us about your business and we'll build a free demo receptionist that answers in your business name.
Prefer a person? Speak to a human: 0417 460 236 or hear our AI now: Call Steve (AI): 03 4328 3434
Don’t take our word for it. Press play.
Press play to hear a real call · call 1 of 6
A house sale quote, taken for the principal
Law firm · new enquiry · 0:00 / 2:33
Listen for: it answers the price question straight, takes every detail and reads it all back.
Real recordings with real callers, shared with permission by businesses we've built AI receptionists for. Some of these businesses are connected to the people behind Aussie AI Agency. To protect privacy, we've deliberately cut out names, phone numbers, emails and business names, and trimmed the calls for length.
What's the underlying architecture of an AI receptionist?
If you want the higher-level overview of what an AI receptionist is before diving into the architecture, that's the definitional companion to this page. Otherwise, here's the engineering view.
Most production AI receptionists in 2026 use what's called a “cascading architecture”: three specialised AI services running in sequence, with each handing off to the next:
Caller's voice  →  [STT: Speech-to-Text]
                   ↓
               [LLM: Large Language Model]
                   ↓
               [TTS: Text-to-Speech]  →  Caller hears response
This is the dominant architecture because each layer can be independently optimised, swapped, and improved. If a better speech-to-text model comes out, you switch only that layer. If you want a different voice, you change only the TTS provider. The trade-off is that the handoffs between layers add latency, usually 100-300 milliseconds in total.
A newer alternative is unified speech-to-speech architecture: a single model that handles voice input to voice output without intermediate text steps. OpenAI's Realtime API, Google's Gemini Live, and xAI's Grok Voice ThinkFast use this approach. Total end-to-end latency targets sub-300ms, which is genuinely human-natural. The trade-off is less flexibility. You can't independently swap layers, and the unified model handles all decisions including tone, pacing, and intent recognition together.
Most Australian AI receptionist providers (including Aussie AI Agency, Sophiie AI, Johnni AI, AiDial, Smith.ai) currently use cascading architecture because:
- It's more mature and battle-tested in production
- Industry-specific compliance configuration is easier when the LLM layer is separately controllable
- Voice swapping (different accents, genders, languages) is easier
- Debugging is much easier, because you can inspect the transcript, the LLM's response, and the TTS output independently
- Function calling and API integration are more reliable
Unified speech-to-speech models will likely become the dominant architecture within 2-3 years as they mature, but for current production use, cascading remains the reliable choice for compliance-regulated industries.
A more complete view of the production architecture
In practice, AI receptionist systems include several additional layers beyond just STT/LLM/TTS:
- Telephony layer: SIP trunks, VoIP providers (commonly Twilio in Australia), call routing logic
- Voice activity detection (VAD): distinguishes when the caller is speaking vs paused vs finished
- Turn-taking logic: handles interruptions, overlapping speech, and conversational pacing
- Context management: maintains the full transcript and business context across the call
- Function calling layer: translates LLM decisions into API calls to your business software
- Observability layer: logs every call, traces latency by stage, records quality metrics
- Escalation logic: confidence scoring that decides when to hand off to humans
When a vendor says “AI receptionist,” they're packaging all of these layers into a single product. The headline simplicity (“AI answers the phone”) hides genuine engineering complexity underneath.
What happens in each step of an AI receptionist call?
Here's what happens in each step of a typical AI receptionist call, with realistic timing for each stage:
Step 1: Call routing (typically <100ms)
Your business phone line is forwarded to a virtual phone number managed by the AI receptionist provider. Most Australian providers use Twilio for telephony (the dominant carrier-agnostic platform), though some use direct SIP trunk connections to Australian carriers like Telstra or Optus.
When a caller dials your usual business number, the call routes through SIP/VoIP to the AI's number. The caller doesn't see this redirect. They think they're calling you directly, because they are. Your number stays yours; only the call destination changes.
Step 2: Speech-to-text (STT), typically 100-300ms per turn
The caller's audio is streamed in real time to a speech recognition service. Modern AI receptionists commonly use:
- OpenAI Whisper / Whisper Large v3 ↗: high accuracy, supports 99+ languages
- Deepgram Nova-2: purpose-built for real-time call audio, lowest latency
- Google Cloud Speech-to-Text: strong Australian English accent handling
- Azure Cognitive Services Speech: enterprise-grade, ISO compliance
- AssemblyAI: strong on accents and noisy environments
The best of these achieve word error rates around 4.9% on benchmark English audio (per NIST testing), with Australian accent accuracy typically 92-96% on clean phone audio. Background noise, strong accents, and conversational speech reduce accuracy, though it's well past the point (around 2024) where this was a regular problem.
Step 3: Large language model (LLM), typically 300-500ms per turn
The transcribed text is fed to a large language model with a structured system prompt that defines:
- The business name, services, and opening hours
- The receptionist's persona (name, tone, pacing, escalation rules)
- The booking system and integrations available
- Industry-specific compliance rules (AHPRA framework for healthcare, AFSL/NCCP for finance, state-based conveyancing law, etc.)
- The full transcript of the conversation so far
- Available “tools” the LLM can call (book appointment, transfer call, send SMS, look up customer)
Common LLM choices for AI receptionists:
- OpenAI GPT-4 / GPT-4o: high quality, strong function calling
- Anthropic Claude (Sonnet / Opus) ↗: strong instruction following, lower hallucination rates, preferred for compliance-sensitive applications
- Google Gemini Pro / Flash: competitive quality, Google ecosystem integration
- Meta Llama 3.1 / 3.3 (self-hosted): open-source option for teams that want full control over where the model runs
The LLM generates a structured response: what to say next, what action to take (book, transfer, escalate), and any data to capture.
Step 4: Text-to-speech (TTS), typically 200-400ms per turn
The LLM's text response is sent to a voice synthesis service that produces natural-sounding audio:
- ElevenLabs ↗: industry-leading voice quality, supports custom Australian voices
- Cartesia Sonic: purpose-built for low-latency streaming, sub-200ms first audio
- Azure Neural TTS: enterprise-grade with multi-region Australian deployment
- PlayHT: competitive on voice variety
- OpenAI TTS: bundled with GPT-4o for unified workflows
The audio streams back to the caller as it's generated, so the caller doesn't wait for the full response to be synthesised before hearing the first words.
Step 5: Workflow actions (these run in parallel with the conversation)
While the conversation continues, the AI triggers actions in your business software through function calling. Example workflow during a single call:
- Caller mentions they want to book, so the AI calls
check_availability(date_range)against your practice management API - Available slots come back and the AI offers them to the caller
- Caller confirms, and the AI calls
create_booking(patient_id, slot_id)and gets confirmation - AI calls
send_sms(phone, confirmation_message)in parallel - AI calls
log_lead(name, contact, reason)in your CRM
The two-stage commit pattern is critical here: the AI never says “you're booked” until the booking API returns success. If the API times out or errors, the AI says “I'll confirm by SMS in the next minute” and handles the actual confirmation asynchronously. It never tells the caller something happened that didn't.
Step 6: Call summary, generated within 60 seconds of the call ending
When the call ends, the AI generates:
- A written summary in plain English (“Mark Henderson called to book a check-up. Booked Tuesday 2:30pm. Existing patient, file updated.”)
- A full transcript of the call
- Structured data extraction (caller name, contact details, reason for call, action taken, urgency level)
- A confidence score on whether anything needs human review
This reaches your team within 60 seconds, usually by email, SMS, push notification, or (where a direct integration has been built) into your practice management system / CRM.
The entire 6-step flow happens for every call. Most callers complete a booking in 60-90 seconds of conversation, which means 4-8 round-trips of STT → LLM → TTS, each adding latency.
Why is latency the most important technical metric for AI receptionists?
“Latency” in AI voice context refers to mouth-to-ear turn gap: the time from when the caller stops speaking to when the AI's response reaches the caller's ear. It's the single most important technical metric for AI receptionist quality, because it determines whether the call feels natural or robotic.
The human reference points
- Natural conversational pause: 200-500ms, feels normal
- Slightly slow but acceptable: 500-1,000ms, noticeable but tolerable
- Awkward delay: 1,000-1,500ms. The caller notices and it feels “robotic”
- Broken: >1,500ms. The caller may hang up or talk over the AI
Research from voice AI specialists like Cresta ↗ and customer experience studies cited by Twilio ↗ and MindStudio ↗ converge on the same threshold: sub-500ms feels human; over 1,000ms degrades the experience rapidly.
The latency budget breakdown in cascading architecture
| Stage | Typical latency | Best systems |
|---|---|---|
| Telephony round-trip | 50-100ms | 30-60ms |
| Voice activity detection (end-of-speech) | 100-300ms | 50-150ms |
| Speech-to-text | 100-300ms | 50-150ms |
| LLM inference (first token) | 300-500ms | 150-300ms |
| Text-to-speech (first audio) | 200-400ms | 100-200ms |
| Network return | 50-100ms | 30-60ms |
| Total | 800-1,700ms | 410-920ms |
Sources: Twilio voice agent latency guide, Cresta engineering blog, MindStudio voice agents low-latency guide, AssemblyAI voice agents documentation.
Most production AI receptionists in 2026 operate in the 600-1,100ms total latency range. The best systems (Aussie AI Agency, top-tier configurations of Sophiie AI, AiDial, premium tiers of Smith.ai) sit at the lower end. Budget tools and poorly-configured systems often exceed 1,500ms.
Why latency varies so much
- Streaming vs batch processing: streaming each stage (sending words as they arrive vs waiting for full sentences) cuts latency significantly
- Geographic proximity: the further the servers are from the caller, the longer each network round-trip takes
- Model size: smaller LLMs respond faster but with lower quality; finding the right size matters
- VAD tuning: overly cautious end-of-speech detection adds 200-400ms of waiting after the caller stops talking
- Function call overhead: when the LLM needs to call your booking API mid-conversation, the round-trip adds 100-500ms
For a calling experience that feels human, latency optimisation is honestly the engineering work that pays off most when you build an AI receptionist. The difference between 600ms and 1,200ms latency is the difference between “I can't tell it's AI” and “obviously a robot.”
How does an AI receptionist integrate with my business software?
It connects to your calendar, booking system or CRM through a direct API, a middleware tool like Zapier, or a custom connector, so it can check availability, create bookings and log every call. With Aussie AI Agency, Google Calendar booking is built in; with your other systems Steve works alongside them, and a direct integration is quoted on request.
On its own, an AI receptionist isn't much use. Its value comes from completing actions in the software you already use. There are three main integration patterns:
Pattern 1: Native API integration
The provider has built a direct connection to specific software, using that software's API to check availability and create bookings in real time during the call. At Aussie AI Agency, Google Calendar is the connection we've built. With other booking systems and CRMs, Steve works alongside them: he sends your team the details by SMS and email within seconds, plus the portal, and your team adds them. A direct integration is quoted on request.
- Best for: Widely used calendars and booking systems
- Reliability: Highest, because purpose-built connections handle edge cases
- Coverage: Limited to software the provider has built for
Pattern 2: Webhook + middleware (Zapier, Make, n8n)
The AI receptionist sends structured data via webhook to an automation platform, which routes it into your software.
- Best for: Less-common software or custom workflows
- Reliability: Medium. It depends on the middleware layer
- Coverage: Universal. Zapier supports 6,000+ apps
Pattern 3: Custom API integration
For enterprise or niche software, the provider builds a custom connector.
- Best for: Unusual proprietary systems
- Reliability: High, if built well
- Cost: Often a one-off integration fee ($500-$3,000)
The data flow during a typical call
For a medical clinic booking a new patient:
- Call arrives → AI greets caller
- Caller provides name, phone, reason for visit
- AI calls
lookup_patient(phone)→ existing patient? No - AI captures structured intake data during natural conversation
- AI calls
check_availability(practitioner, date_range)→ returns slots - AI offers slots, caller picks one
- AI calls
create_patient(name, phone, dob, reason)→ patient ID returned - AI calls
create_booking(patient_id, slot_id, type)→ booking confirmed - AI calls
send_sms(phone, confirmation_template, slot_details)→ SMS sent - AI confirms verbally to caller
- AI calls
log_call(transcript, summary, structured_data)→ archived
That's 7 API calls in a 90-second conversation, all happening in parallel with the natural-sounding voice interaction.
The integration quality directly determines the AI receptionist's value. A provider with excellent voice quality but a weak connection to the clinic's booking system is less useful to a medical clinic than a provider with decent voice and a deep, reliable one. When evaluating providers, the integration depth question matters as much as the voice quality question.
How does an AI receptionist know when to escalate to a human?
Knowing when to stop and hand off is one of the hardest engineering problems in AI receptionist design. A poorly designed system tries to answer everything and hallucinates; a well-designed system explicitly escalates when:
Trigger 1: Confidence scoring below threshold
Modern LLMs can produce a confidence score on their own response quality. When confidence drops below a configured threshold (e.g., 70%), the system flags the response for human review rather than committing to an answer.
Trigger 2: Keyword/intent-based escalation
Specific phrases trigger automatic escalation regardless of LLM confidence:
- “Emergency” / “urgent” / “ambulance” / “000”: immediate human handoff
- “Complaint” / “lawyer” / “lawsuit”: escalation to senior team
- Healthcare-specific: “chest pain” / “bleeding” / “overdose”: immediate clinical escalation, 000 directive
- Pharmacy-specific: S4/S8 medication names: escalation to pharmacist
- Financial: “fraud” / “scam” / “stolen”: escalation to compliance
Trigger 3: Caller request
When a caller asks for a human (“Can I speak to a real person?”), the AI immediately offers transfer or callback options without trying to convince the caller to continue with AI.
Trigger 4: Out-of-scope topic detection
For compliance-regulated industries, the LLM is configured to recognise when callers ask for advice the AI is not authorised to provide:
- Medical: clinical diagnosis questions → escalation to practitioner (AHPRA-regulated healthcare)
- Financial: product recommendations → escalation to AFSL-credentialed adviser (AFSL-regulated financial planning) or NCCP-licensed broker (NCCP-regulated mortgage broking)
- Legal: specific legal opinion → escalation to solicitor (state-based conveyancing)
- Pharmacy: dosing questions → escalation to pharmacist (S4/S8 medication escalation)
Trigger 5: Sentiment detection
When the caller's tone indicates frustration, distress, or anger, the system can route to humans even if the call would otherwise be routine. Aussie AI Agency's healthcare overrides specifically include this trigger, so bereavement-tone or panic-tone callers always reach a human.
The compliance distinction matters most in Australian regulated industries. A generic global AI receptionist may handle escalation poorly because it wasn't designed for AHPRA, AFSL, NCCP, or state-licensed legal scope. Industry-specific AI receptionists bake the escalation rules into the system design from day one. Where you are matters too: Sydney businesses and Melbourne businesses face state-specific compliance variations.
Common questions about how AI receptionists work
A note on this technical guide
This guide is published by Aussie AI Agency. We're an Australian AI receptionist provider, so we have a commercial interest in helping you understand the category.
Where the technical details come from
The technology citations (OpenAI Whisper, Anthropic Claude, ElevenLabs, Deepgram, Cartesia, Twilio, Azure Speech) are all real production services that AI receptionist providers use. Specific latency figures and word error rates are sourced from public vendor documentation, NIST benchmarks, and engineering blogs from Twilio, AssemblyAI, Cresta, and MindStudio (cited where used).
Where we draw the line on technical disclosure
We don't disclose Aussie AI Agency's specific stack choices in detail. That's competitive engineering, not category education. What we do share: cascading architecture is standard, our latency targets sub-800ms, Google Calendar booking is built in (with other systems Steve works alongside them), and caller data is encrypted in transit and at rest and handled under the Privacy Act 1988 (Cth) and the Australian Privacy Principles. See our privacy policy for the service providers we use and where they process data.
A caveat on technology change rates
Voice AI technology moves fast. Models cited today (GPT-4o, Claude Sonnet, ElevenLabs Turbo, Cartesia Sonic) may be superseded in 6-12 months. This page is reviewed quarterly to keep citations current.
If you spot a technical inaccuracy, email niel@aussieaiagency.com.au.
Want to test the technology for yourself?
The fastest way to evaluate AI receptionist technology is to hear one on real calls. Press play on the recorded calls near the top of this page, then get a free demo built for your business and try it yourself. Listen for:
- Latency: does it respond like a human (under 500ms) or feel robotic (over 1,000ms)?
- Voice quality: does the Australian accent sound natural?
- Conversation handling: try interrupting mid-sentence; does it recover gracefully?
- Action completion: try booking; does the booking actually happen?
These four questions tell you more about quality than any vendor marketing claim. After the demo, explore the industry pages for compliance-specific implementation details, or our pricing page for plans and what's included.
No obligation · Niel calls you to book a time
Plans from $149/month + GST.
After every call, the message is in your pocket
Seconds after a call ends you get a text and an email: who rang, what they want, how urgent it is and when to ring them back. Urgent calls can come straight through to you.
- No more listening to voicemails
- Every caller's name, number and reason
- Call back the right people first
Text message · just now
Email · call summary
- Caller
- Steve
- Wants
- Quote, Somerset 17
- Call back
- Today, 4pm
- Urgency
- Normal
Example based on the caravan call above.
Manage every call from your dashboard
Every call lands in your own dashboard: who rang, what they need and what to do next. Tap Done, assign it to someone or add a note. Add as many staff as you like, there’s no limit.
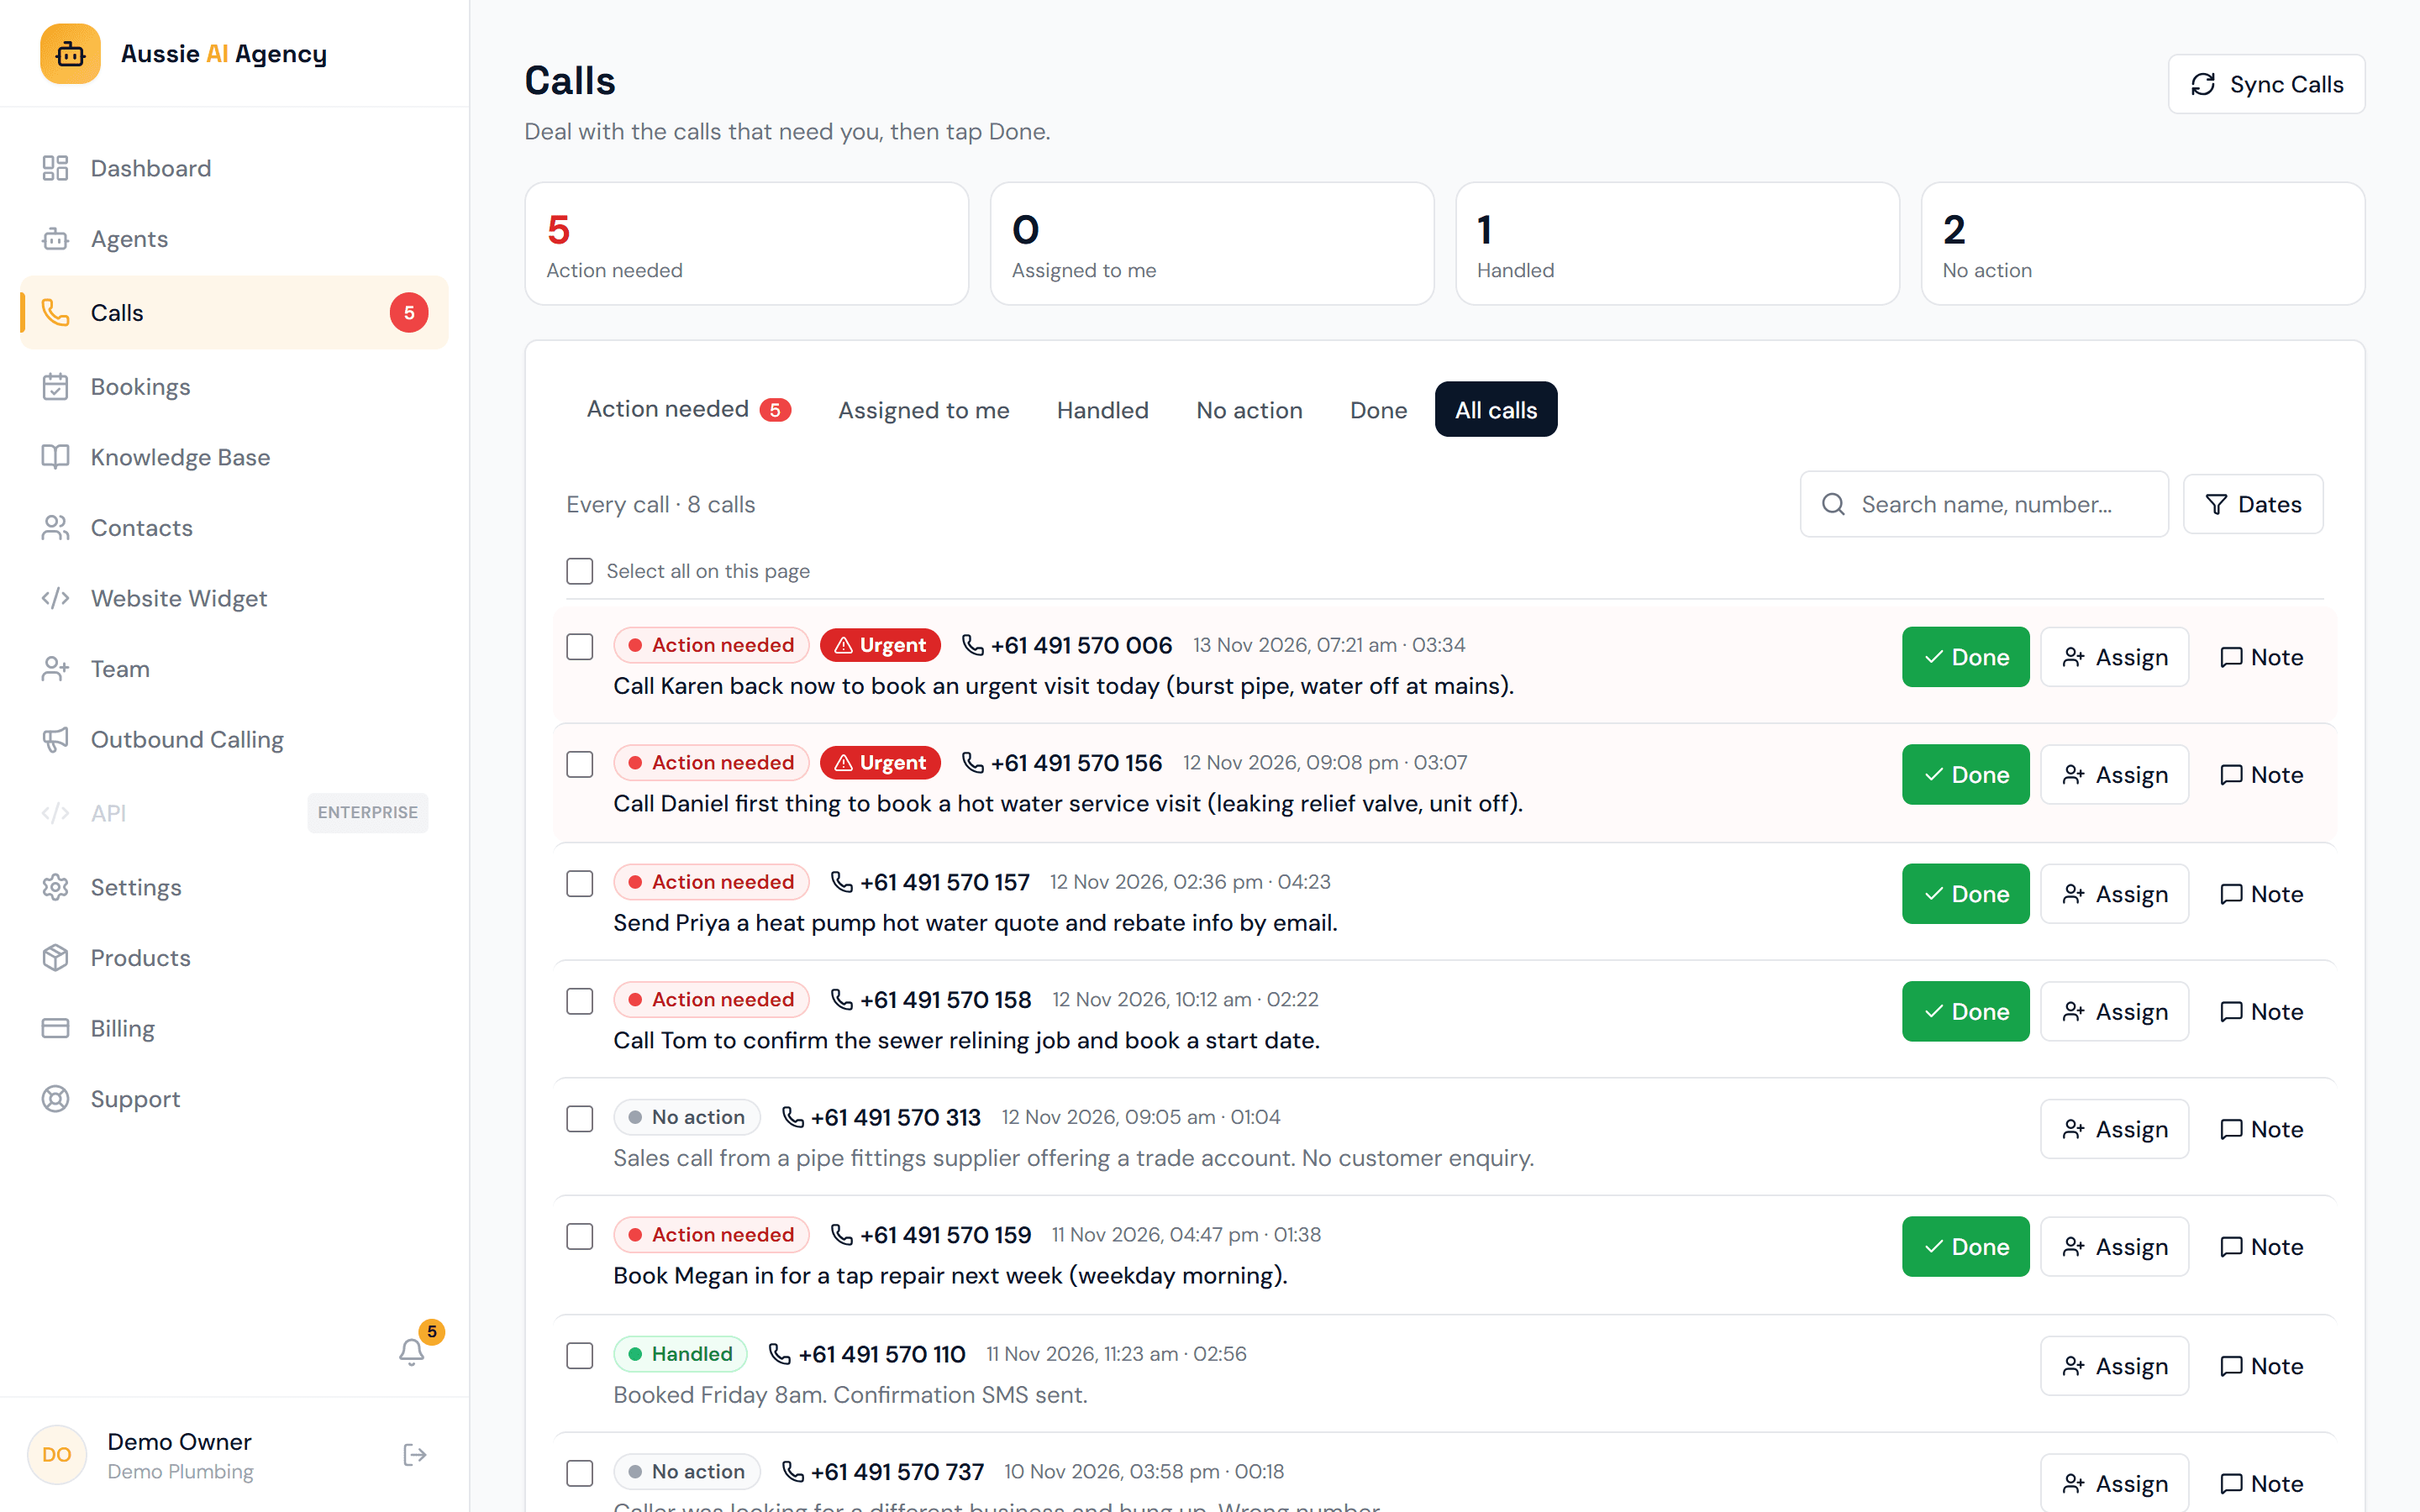
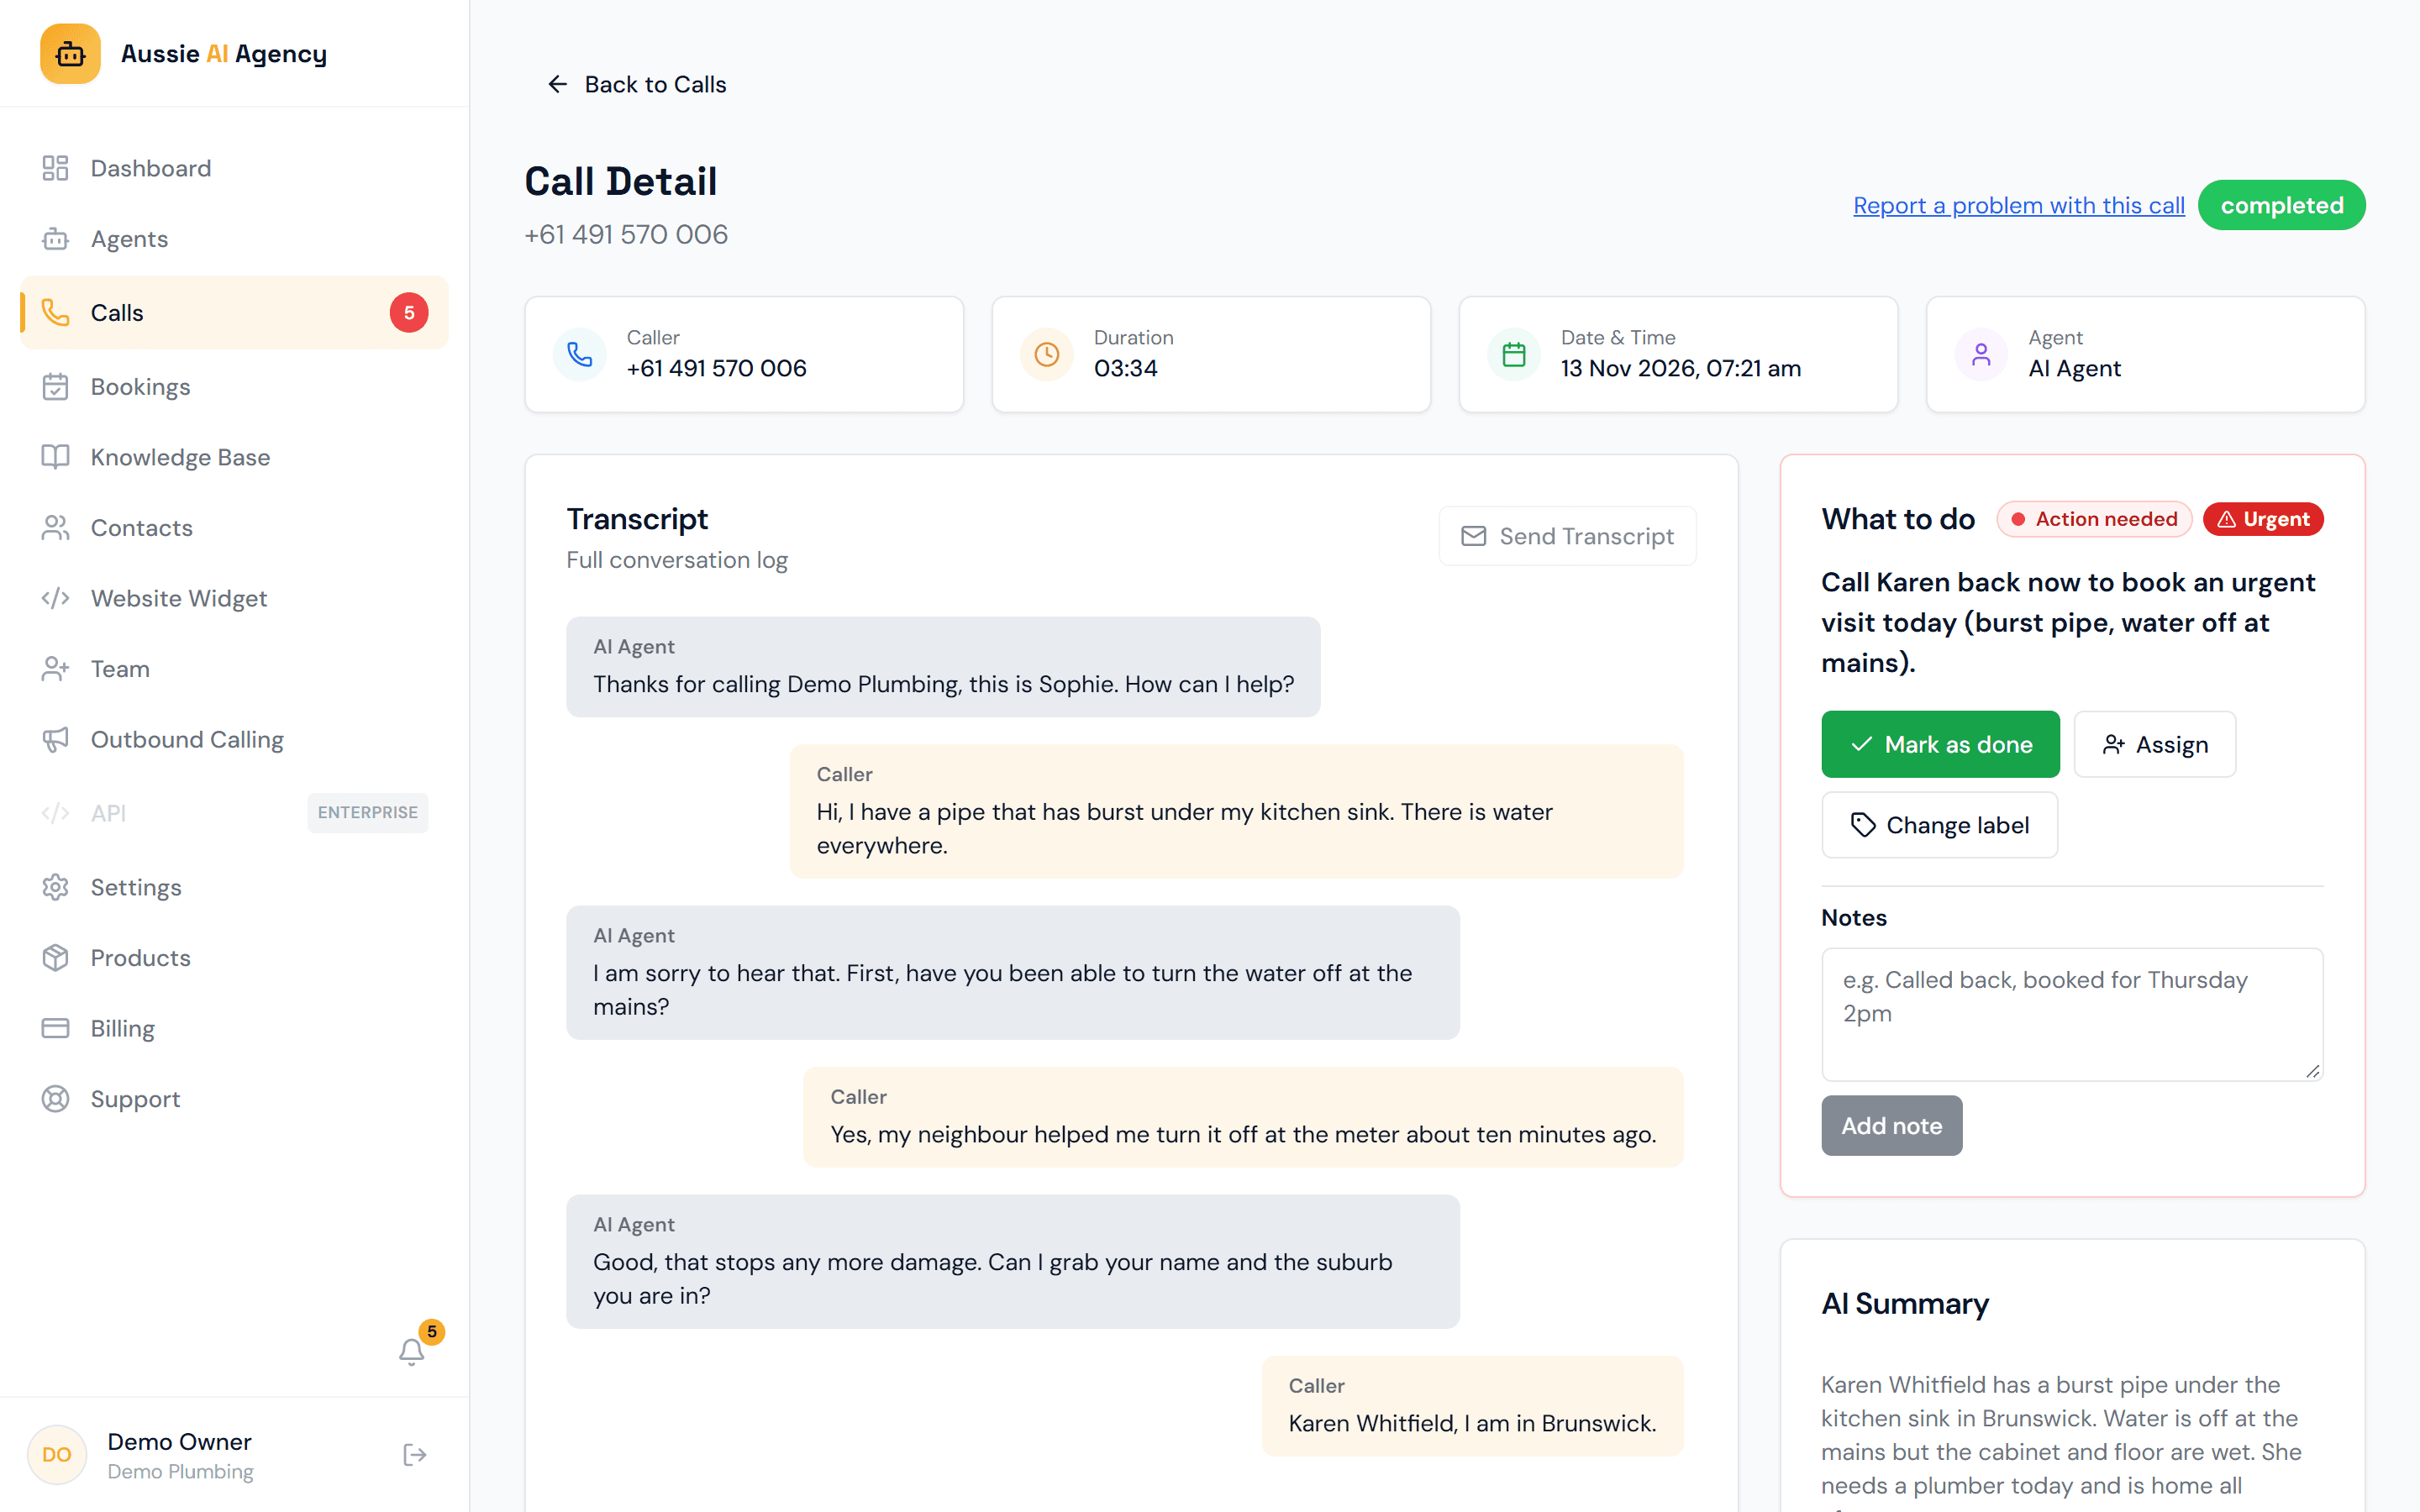
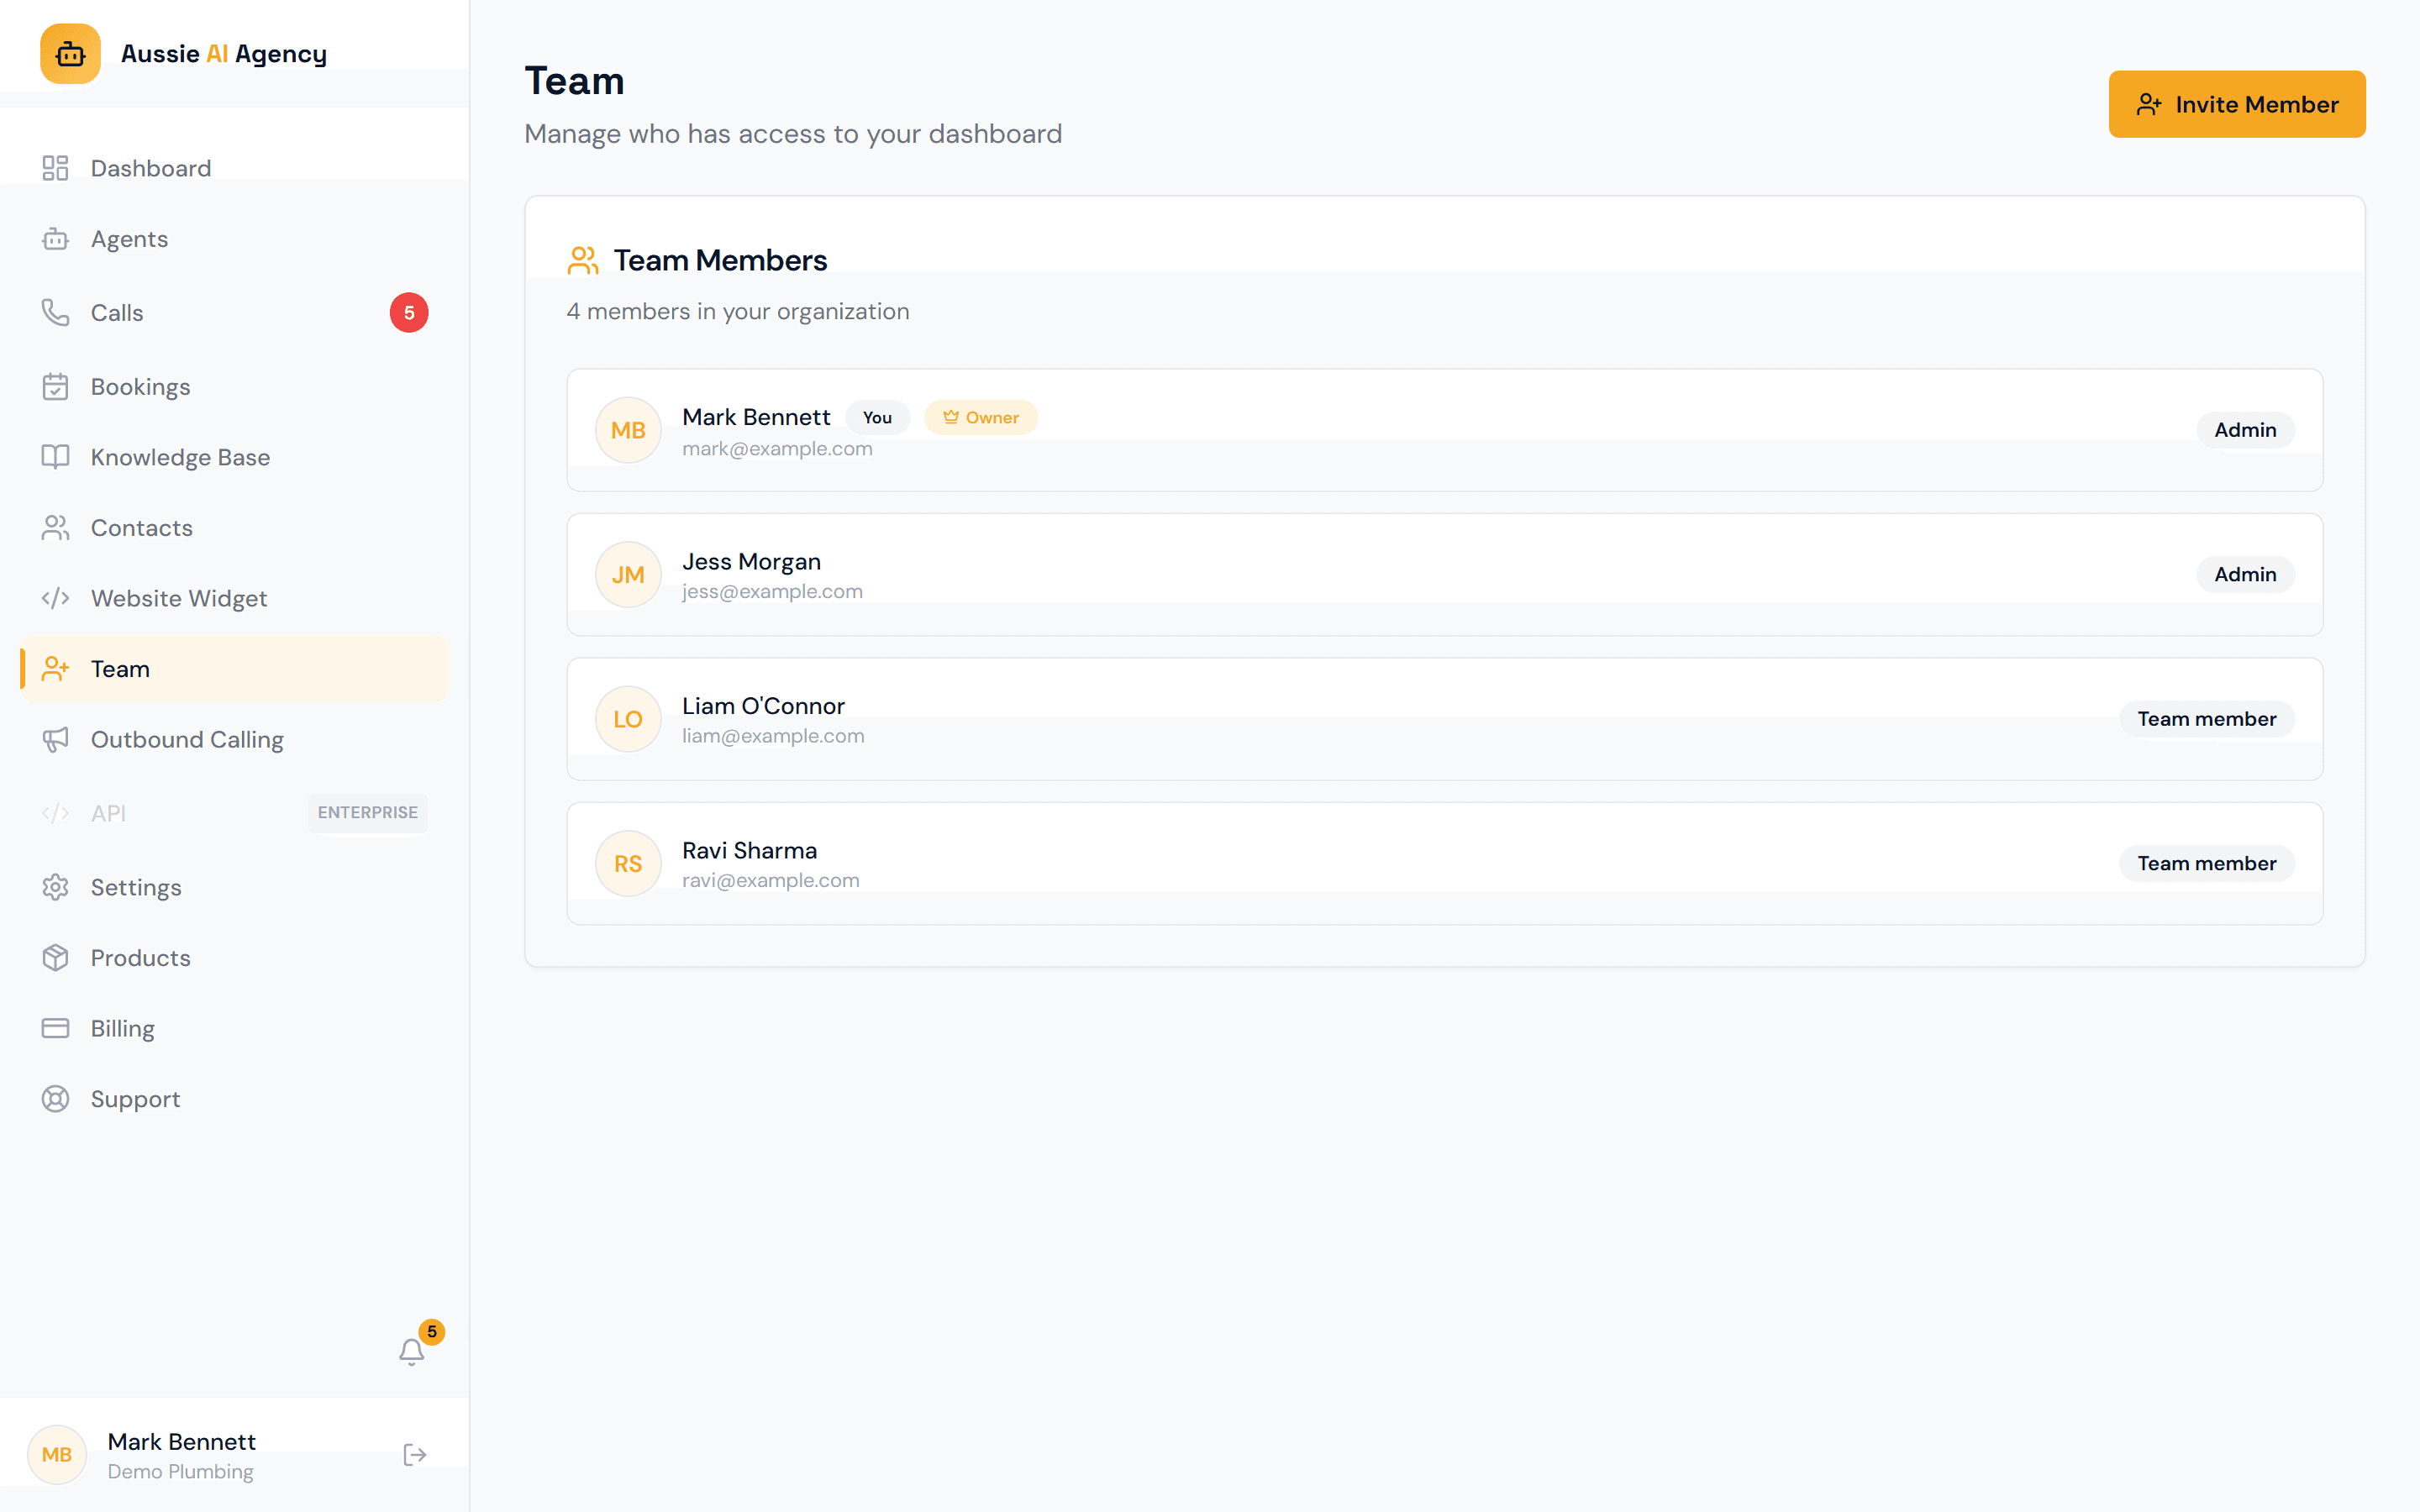
Example dashboard with sample data.
Real customer
Hear it from a plumber who uses it
He’s on the tools all day, so his AI receptionist answers the calls he can’t. Here’s what he thinks, in his own words.
Get my free demo